What is Managed Database as a Service (MDBaaS)? Clearing the Biggest Misconceptions

Every enterprise application eventually runs into the same quiet problem: the database underneath it outlives every sprint, every roadmap, and usually every engineer who set it up.

As organisations spread workloads across MySQL, PostgreSQL, MongoDB, Redis and half a dozen other engines, keeping all of them patched, backed up, monitored, secured and available around the clock stops being a task and starts being a full-time operating burden. Provisioning a database takes minutes. Running it reliably for years does not.

 That gap between standing up a database and operating one is exactly what Managed Database as a Service (MDBaaS) exists to close. And with AI workloads now adding a new layer of data demands, that gap is only getting more expensive to ignore.

What Managed DBaaS Actually Means

Managed DBaaS isn’t “a database in the cloud.” It’s a shift in who is responsible for keeping that database alive.

The provider takes on:

  • Provisioning and configuration
  • High availability and replication
  • Backup and point-in-time recovery
  • Patching and version upgrades
  • Monitoring and alerting
  • Scaling and capacity management
  • Failover and recovery

The enterprise keeps control of:

  • Schemas, queries, and indexes
  • Users, roles, and permissions
  • Data governance and access policy
  • Application-level architecture

Think of it like an apartment building. Your data the schemas, records, and business logic is your apartment. You decide what goes in it and who gets a key. The control plane is building management: the plumbing, the elevators, the security desk, the people who show up when something breaks at 3 a.m. so you don’t have to.

That’s the real test of a mature platform: not just which database engines it runs, but how well the “building management” layer behind them actually works.

Four Things People Get Wrong About Managed DBaaS

“A cloud database is already a managed database.” Not necessarily. Running a database on a cloud VM (IaaS) can still leave your team installing the engine, configuring replication, applying patches, and getting paged at night. A useful gut-check: who owns this database when it fails at 3 a.m.? If the answer is your own ops team, you’re still running a self-managed setup —  the cloud infrastructure may be managed, but the database itself is still your operational responsibility..

“Managed DBaaS means we don’t need DBAs anymore.” It removes the repetitive operational load patching, backups, routine failover — not the need for database expertise. Query optimisation, schema design, indexing, and performance engineering  still require database expertise. A poorly written query is still a poorly written query, managed platform or not.

“Managed means we lose control of our data.” No the provider manages the platform, not your data governance. A well-built DBaaS platform should still hand you encryption, private networking, role-based access control, and audit logging, so your team retains oversight of who touches what.

“High availability and disaster recovery are the same thing.” HA keeps an application running when a single component fails. DR is what gets you back up after something bigger a site or regional outage. They solve different problems, and both matter for anything mission critical. The two numbers to ask about are RPO (how much data you can afford to lose) and RTO (how fast you need to be back up) “we offer high availability” on its own isn’t a specification.

Databases Aren’t One-Size-Fits-All Anymore and AI Is Part of Why

Most enterprises today aren’t running one database; they’re running several, each doing a different job:

  • Relational engines (MySQL, PostgreSQL, MSSQL and MariaDB) still anchor transactions, financial records, and anything that needs strict data integrity.
  • Non-relational engines (MongoDB, Redis, Cassandra, ScyllaDB, OpenSearch, ElasticSearch, Hadoop, and Couchbase) handle flexible schemas, high-throughput workloads, caching, real-time applications, powering log analysis, full-text search, and large-scale querying.

And then there is AI.

AI may be the application layer getting the attention, but databases remain the data layer that makes it possible.

AI applications depend on large volumes of reliable data for training, retrieval, context and inference. Retrieval-Augmented Generation (RAG) and semantic search increasingly rely on vector search capabilities to find information based on meaning rather than just keywords. In-memory databases can provide low-latency access to frequently used context, session state and application data.

At the same time, the underlying relational and NoSQL databases still need to store the business and operational data that AI applications depend on.

The interesting question today isn’t simply relational versus non-relational.

It is:

How can different database technologies work together reliably, while reducing the operational complexity of managing them?

Where Yntraa Cloud’s MDBaaS Fits

This is the operating model Yntraa MDBaaS is built around: bringing multiple database technologies under one managed layer instead of leaving each one as its own silo.

  • Yntraa Cloud SutraDB covers relational engines for transactional and structured workloads,  including MySQL, PostgreSQL, Microsoft SQL Server  and MariaDB.
  • Yntraa Cloud FlexiDB covers non-relational engines for flexible-schema, AI, RAG, vector search, high-throughput, real-time,  search and analytics workloads, including MongoDB, Redis, Cassandra, ScyllaDB, OpenSearch, Elasticsearch, Hadoop and Couchbase, depending on the use case.

Across all of it, the model stays consistent: provision, configure, monitor, back up, scale, secure, and recover handled by the platform, so your team spends its time on the data and the application.

 For Indian enterprises, where primary databases, backups and replicas are stored, and who can access them, can be an important consideration for regulatory, sectoral and internal governance requirements.

This makes infrastructure location, security, compliance and local operational support increasingly relevant considerations for organisations managing critical data.

The Future of Managed Database as a Service

Database management is moving beyond simply keeping a database online. The next generation of MDBaaS platforms will increasingly focus on automation, observability, intelligent performance management, multi-database operations and AI-ready data infrastructure.

Enterprises may continue to use different database technologies for different workloads, but the operational experience doesn’t have to be fragmented.

The opportunity for MDBaaS is to bring these environments together under a consistent management model giving organisations the flexibility to choose the right database for the right workload without multiplying operational complexity.

The Bottom Line

Managed DBaaS isn’t about eliminating database expertise.

It’s about putting that expertise where it creates the most value on architecture, query design, performance, data strategy and application outcomes rather than patch cycles, routine backups and 3 a.m. failovers.

As databases become increasingly important to both traditional applications and AI-driven workloads, the ability to operate them reliably, securely and efficiently will become just as important as the database technology itself.

Yntraa Cloud’s MDBaaS is built around that shift: helping organisations move from managing database infrastructure to consuming database capability.
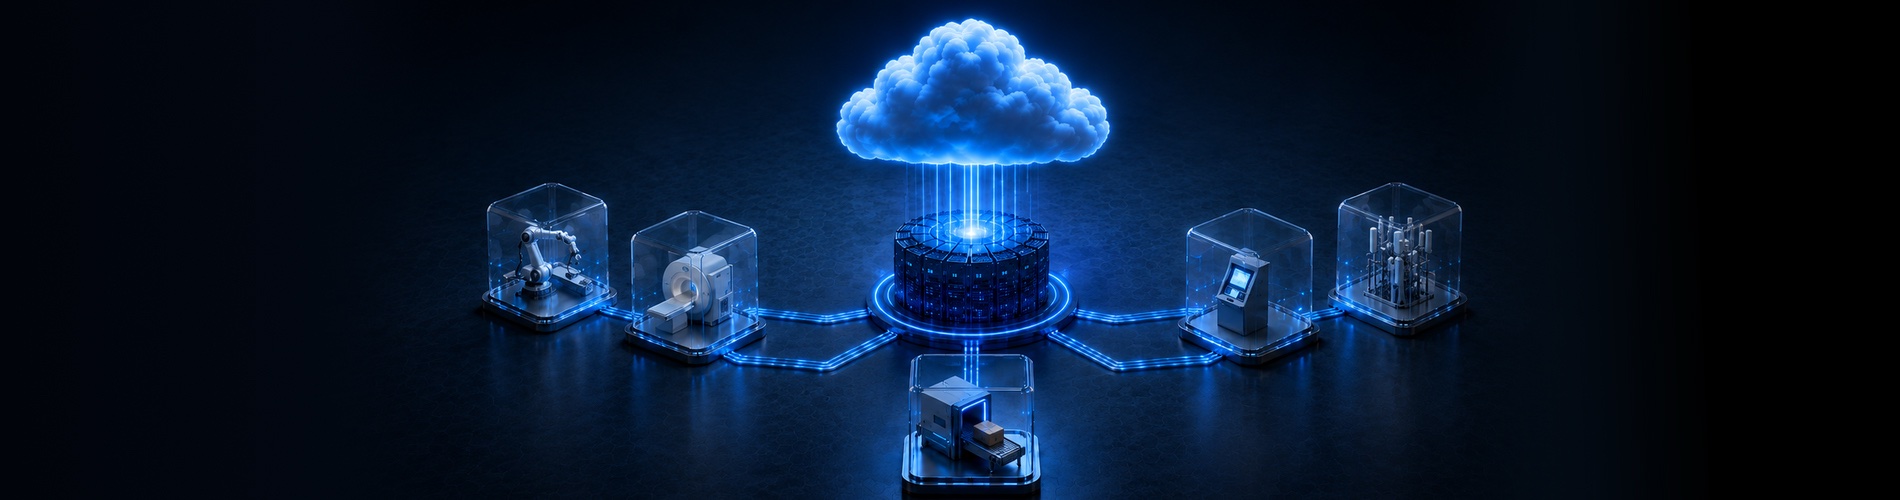
How Compute-as-a-Service is Accelerating Digital Transformation Across Industries in India

For decades, computing power was something enterprises built, not bought. Server rooms, procurement cycles, CapEx locked into multi-year depreciation schedules – this was the price of doing business at scale, and it meant infrastructure decisions were made years ahead of actual demand. That model is breaking down, and fast. Compute as a Service has flipped the equation: compute is now provisioned as elastic, API-driven capacity – VMs, containers, bare metal, GPU instances – spun up in minutes and billed against actual consumption rather than peak-case sizing.

The shift matters because compute has quietly become the bottleneck of the digital economy. Every application running and processing, AI model’s training and inference cycle, every real-time analytics pipeline processing streaming data, every customer-facing app running microservices under variable load depends on raw processing capacity behind the scenes. Enterprises that once measured infrastructure readiness in procurement and rack-deployment cycles now need to provision capacity in hours, not months. Cloud compute services close that gap – decoupling business velocity from hardware lead times.

Where the Demand Is Actually Coming From

India illustrates this better than almost any other market. Compute as a Service India is scaling in step with the country’s broader digitisation push, and the technical shape of that demand looks different sector by sector.

In banking and financial services, core banking, ATM operation, real-time fraud detection models run as low-latency inference pipelines that need to score transactions in milliseconds, not batches. UPI-scale transaction processing means throughput spikes tied to payday cycles, festival sales, and end-of-month settlement windows – traffic patterns that can multiply several times over within hours. This is a workload profile suited to horizontal autoscaling and containerised microservices, not statically sized VM clusters that sit half-idle on a normal Tuesday and buckle under load on a peak one.

In healthcare, telemedicine platforms run on bursty, session-based compute – video processing, queuing, and scheduling systems that need to scale out fast when demand spikes. Diagnostic AI tools, particularly imaging models doing inference on X-rays, MRIs, or pathology slides, are GPU-dependent and need burstable access to accelerated compute rather than dedicated GPU clusters sitting provisioned year-round for occasional use. Public health events compound this further: demand can move from baseline to multiples of normal volume within days, which is an autoscaling problem, not a capacity-planning one.

Manufacturing is quietly becoming one of the largest consumers of compute as factory floors get instrumented with IoT sensors – vibration monitors, thermal sensors, machine vision systems on the line – generating continuous telemetry that needs edge-adjacent processing to catch anomalies before they cause downtime. This pushes workloads toward edge nodes and regional compute closer to the plant, since round-tripping every sensor reading to a distant central data center introduces latency that defeats the purpose of real-time monitoring. Predictive maintenance models retrain periodically on aggregated data, which needs a different compute profile again – batch-oriented, compute-intensive, scheduled rather than always-on.

And media and entertainment, particularly OTT and gaming, needs compute that can absorb order-of-magnitude traffic spikes around a single release, a live sports stream, or a game launch – then scale back down just as fast. This is the canonical case for serverless and container-orchestrated infrastructure: provisioning for peak load year-round would mean paying for idle capacity 350 days a year to cover five days of demand.

None of these workload patterns tolerate the fixed, monolithic server architecture of a decade ago. They demand infrastructure that can autoscale horizontally, deploy across multiple availability zones for fault tolerance, and mix compute types – VMs, containers, bare metal, GPU-accelerated instances – within a single architecture, without an enterprise having to predict its own peak load three years in advance.

Why Elasticity Beats Ownership

That unpredictability is the real argument for on-demand compute infrastructure. A retail platform doesn’t need the same processing power in October that it needs during a festival sale. A fintech startup doesn’t know today what its transaction volume will look like at Series B. Fixed infrastructure forces these businesses to either overprovision – and bleed capital sitting idle – or underprovision, and risk outages at the worst possible moment. CaaS solutions remove that dilemma entirely: capacity tracks actual demand, not forecasted demand.

This elasticity also reshapes how IT teams think about growth. Scalable compute infrastructure means a business can move from a regional pilot to a national rollout without a hardware refresh cycle sitting in the critical path. Engineering teams stop asking “do we have the servers for this” and start asking “how fast can we ship.” That’s a meaningful cultural shift inside enterprises that have historically treated infrastructure as a constraint rather than an enabler.

The Macro Picture: Compute as National Infrastructure

Zoom out, and this is really about digital transformation in India at the macro level. The government’s push toward a trillion-dollar digital economy, the proliferation of Tier-2 and Tier-3 city internet users, and the rise of API-first business models in retail, logistics, and public sector governance all assume compute is available, affordable, and elastic. Compute as a Service is the plumbing that makes that assumption true. Without it, ambitious digital policy remains aspirational; with it, execution becomes possible at national scale.

For enterprises specifically, this translates into IT infrastructure modernization – not as a one-time migration project, but as an ongoing capability. Legacy data centres depreciate, need refresh cycles, and lock organisations into architectural decisions made years earlier. A CaaS model sidesteps that trap entirely, letting IT leadership modernize continuously rather than in painful multi-year leaps. As enterprises layer in machine learning and generative AI workloads, this modernisation increasingly means building on AI-ready compute infrastructure — capacity designed from the ground up for GPU-intensive, high-throughput workloads rather than retrofitted general-purpose servers.

Where Yntraa Cloud’s Compute Services Fit Into This Shift

Yntraa’s Compute Services are built for exactly this transition. It gives enterprises access to on-demand, scalable computing resources, spanning End-User Compute, Virtual Machines, Bare Metal Servers, Managed Kubernetes, Containers, and Serverless Compute, without the constraints of conventional infrastructure ownership. Instead of locking into a single deployment model, organisations can choose the environment suited to each workload, whether that’s high-performance computing, microservices, or event-driven applications.

This flexibility is backed by the same operational discipline that underpins the broader Yntraa Cloud platform: layered security and IAM controls, multi-zone and multi-region deployment options for fault tolerance, and pay-as-you-go, fixed-term, and flexible saving plans that let cost track actual usage rather than worst-case provisioning. What makes this relevant beyond infrastructure specs is sovereignty. As Indian enterprises and government bodies scale their digital operations, the ability to modernize IT while keeping data within Indian jurisdiction becomes a strategic requirement, not a compliance checkbox. Yntraa’s compute offerings are built to deliver that – enterprise-grade, AI-ready capacity that lets Indian organisations move at the speed digital transformation demands, without compromising on control over where their data lives.

Hybrid, Multi-Cloud, or Full Migration? Strategy Frameworks That Actually Work 

Cloud transformation decisions today are no longer about whether to migrate, but about designing the right operating model for scale, resilience, compliance, and long-term business control. For large enterprises, the debate between full cloud migration vs hybrid cloud is fundamentally an architecture and governance question – not just an infrastructure decision. 

A robust cloud migration strategy framework must begin with workload-level technical assessment rather than provider-led migration templates. The most effective enterprises first classify applications across business criticality, latency sensitivity, data residency, compliance exposure, and modernization readiness. 

For example, transactional core systems such as ERP, banking workloads, manufacturing control systems, and low-latency databases often require deterministic performance and tighter governance controls. These are frequently better suited for hybrid environments where sensitive workloads remain on private infrastructure or sovereign cloud zones, while analytics, AI, customer applications, and burst workloads scale on public cloud. 

This is where the conversation around multi cloud vs hybrid cloud benefits become important.  

Hybrid cloud refers to workload orchestration across on-premise/private cloud and public cloud environments. The key advantage lies in workload portability while retaining control over regulated or latency-sensitive systems. Multi-cloud involves using multiple public cloud providers simultaneously – typically for resilience, best-of-breed services, regional coverage, and avoidance of provider concentration risk. The distinction matters because the operating complexity differs significantly. 

A hybrid model demands integration across network fabrics, identity layers, observability stacks, and security controls between private and public environments. A multi-cloud model introduces additional layers across: 

  • API abstractions  
  • service interoperability  
  • policy enforcement  
  • cost governance  
  • cross-cloud disaster recovery  
  • data synchronization architectures  

This is why a successful enterprise cloud migration strategy must be driven by architecture principles, not procurement decisions. 

The Strategy Framework That Actually Works

A mature cloud adoption strategy for enterprises follows five technical layers. 

1. Workload Rationalization Framework: Before migration, workloads must be classified using the 6R/7R model: 

  • Rehost 
  • Replatform  
  • Refactor  
  • Repurchase  
  • Retain  
  • Retire  

This stage requires dependency mapping across applications, databases, middleware, APIs, and network zones. A monolithic legacy application tightly coupled with Oracle databases and internal authentication systems may not be suitable for direct migration without refactoring. In contrast, stateless web applications or containerized microservices can move faster into public cloud environments. 

2. Landing Zone and Governance Design: A strong hybrid and multi cloud architecture strategy requires standardized landing zones that define: 

  • network segmentation  
  • IAM policies  
  • logging standards  
  • backup frameworks  
  • encryption baselines  
  • DR policies  
  • cost tagging structures

Without this layer, enterprises face uncontrolled sprawl within months of migration. 

3. Data Gravity and Performance Modeling: Migration strategy must account for data gravity. High-volume data workloads such as AI training clusters, real-time analytics engines, or compliance archives often influence infrastructure decisions more than applications themselves. Data egress costs, replication latency, and sovereignty mandates often make hybrid or multi-cloud architectures more viable than full migration. 

4. Operational Model Transformation: Cloud is not simply infrastructure relocation. It requires transformation of operations into SRE, FinOps, SecOps, and platform engineering functions. This is where many enterprises struggle post-migration. 

5. Continuous Optimization: Migration success is measured after cutover. Rightsizing, reserved capacity optimization, observability, performance tuning, and policy compliance become continuous disciplines. This is exactly where managed assurance frameworks become critical.

Why Yntraa’s Cloud Assure Services Become Critical in the Last Mile

The most complex part of any cloud transformation is not migration – it is sustained assurance across hybrid and multi-cloud ecosystems. This is where Yntraa’s Cloud Assure Services becomes strategically significant. 

Designed as an end-to-end managed assurance framework, Cloud Assure addresses the operational complexity that enterprises face across AWS, Azure, Yntraa Cloud, private cloud, and hybrid environments.  

Rather than functioning as a narrow managed service layer, it acts as a single-window governance, operations, and optimization framework. For enterprises building large-scale hybrid and multi cloud architecture strategy, this becomes especially valuable because operational fragmentation is often the biggest risk.

Cloud Assure addresses this through a structured service portfolio that spans the full lifecycle: 

  • Cloud Assessment and Advisory  
  • Cloud Migration Assist  
  • Cloud Monitoring and Notifications  
  • Cloud Operations Management  
  • Cloud Security and Compliance  
  • Cloud Optimization  
  • Cloud Professional Services  

This aligns directly with a mature cloud migration strategy framework. The advisory layer helps enterprises define migration roadmaps, architecture blueprints, compliance alignment, and TCO models before workloads move. 

The migration assist framework supports technical migration patterns across: 

  • Physical to virtual  
  • Virtual to virtual  
  • Cloud-to-cloud  
  • Database migration  
  • Platform migration  
  • Data movement  

including rehost, replatform, and refactor pathways.

This is particularly useful for organizations evaluating full cloud migration vs hybrid cloud, because it allows phased migration waves instead of disruptive large-scale cutovers.

Unified Operations Across Complex Cloud Environments

Where Cloud Assure stands out is post-migration operational maturity. For enterprises operating in hybrid or multi-cloud environments, continuous visibility becomes non-negotiable.

Cloud Assure Services enable:

  • Real-time workload monitoring
  • Incident correlation
  • Threshold-based alerts
  • Infrastructure and application observability
  • Centralized dashboards
  • SLA-driven support models

This is especially important in large enterprises where cloud sprawl leads to performance blind spots. Its 24×7 Cloud Operations Management layer supports proactive maintenance, incident management, compliance enforcement, and predictive operations.

Cost, Governance, and Optimization at Scale

Cloud cost overruns remain one of the largest barriers to cloud ROI. Cloud Assure addresses cost and performance challenges through a structured cloud optimization approach focused on:

  • Identifying unused or unattached resources and consolidating idle capacity
  • Implementing a tagging mechanism to improve visibility and cost allocation
  • Right sizing computing services based on actual workload requirements
  • Leveraging reserved instances (RIs) for long-term cost efficiency
  • Taking advantage of spot instances for short-term, flexible workloads
  • Enabling real-time cost visibility, reporting, and usage insights across environments

For enterprises evaluating multi cloud vs hybrid cloud benefits, cost governance across providers becomes a major differentiator.

Cloud Assure helps unify this under a single control model. Ultimately, the most effective cloud adoption strategy for enterprises is not defined by the environment chosen, but by the operating framework built around it.

Hybrid, multi-cloud, and full migration can all work. What makes them successful is architecture discipline, governance maturity, and continuous assurance. That is where frameworks like Cloud Assure move cloud transformation from migration to long-term business resilience.

From Uptime to Resilience: The Shift in Modern IT Infrastructure Strategy

Downtime today is more than an inconvenience – it’s a direct business risk. Studies show that even a single hour of downtime can cost enterprises thousands to millions of dollars, depending on scale. Meanwhile, modern cloud environments operate under the assumption that failures will happen – not if they happen – driven by hardware faults, human errors, and software bugs. This reality is forcing organizations to rethink a long-standing metric: uptime. 

The Problem with an “Uptime-Only” Mindset 

For years, IT strategies revolved around maximising uptime – keeping systems running as long as possible. While uptime is still important, it is no longer sufficient in today’s distributed, hybrid, and multi-cloud environments.

Traditional uptime strategies focus on prevention: 

  • Avoiding outages.
  • Maintaining redundant hardware  
  • Monitoring system availability  

But modern IT ecosystems are far more complex. With applications spanning cloud, on-premises, and hybrid infrastructures, failure is inevitable. As cloud resiliency principles highlight, organisations must anticipate disruptions and recover quickly without data loss rather than assuming perfect availability.  

This is where the shift begins. 

The Shift: From Uptime to Resilience 

Resilience goes beyond uptime. It is the ability of systems to withstand, adapt to, and rapidly recover from disruptions – while maintaining business continuity. 

Instead of asking, “How do we avoid downtime?,” modern IT leaders ask: 

  • How quickly can we recover (RTO)?  
  • How much data can we afford to lose (RPO)?  
  • Can recovery be automated and tested regularly?  

This shift is driven by three realities: 

1. Failure is inevitable: Cloud-native architectures assume constant risk – failures are part of the system design, not exceptions. 

2. Speed of recovery matters more than prevention: Businesses now compete on how fast they bounce back, not just how long they stay up. 

3. Complexity requires automation: Manual disaster recovery processes are too slow and error-prone for modern environments. 

Why Organisations Must Act Now 

Digital transformation, remote work, and real-time customer expectations have raised the stakes. A delayed recovery can impact: 

  • Revenue and customer trust
  • Regulatory compliance
  • Brand reputation

At the same time, managing resilience internally is challenging. Many organisations lack: 

  • Dedicated disaster recovery (DR) expertise  
  • Standardised processes  
  • Continuous testing mechanisms  

This creates a gap between resilience goals and execution capabilities – and that’s where managed resiliency solutions become critical.

Yntraa Resiliency Assurance Service (RAS): Making Resilience Real 

Yntraa’s Resiliency Assurance Service (RAS) is designed to bridge this gap by transforming disaster recovery from a complex, manual task into an automated, fully managed service.  

Rather than offering just tools, RAS delivers an end-to-end resiliency framework that covers the entire lifecycle of disaster recovery.

1. End-to-End Managed Resilience: RAS handles everything – from DR site analysis and setup to ongoing monitoring, drills, and execution. This eliminates the need for in-house DR specialists and ensures continuous readiness.

2. Automation-Driven Recovery: With features like single-click switchover and switchback, RAS minimizes recovery time objectives (RTO) and reduces human intervention. Automated DR drills allow organizations to test resilience without disrupting operations.  

3. Real-Time Visibility & Control: RAS provides a centralized dashboard with real-time RPO/RTO tracking and health alerts, enabling proactive decision-making and immediate response to issues.  

4. Hybrid & Multi-Environment Support: Modern enterprises operate across diverse environments. RAS supports physical, virtual, cloud, and hybrid infrastructures, ensuring consistent resiliency across the entire IT landscape.  

5. Reliable Failover Execution: Failover and failback processes are fully managed, including automated network and DNS changes – ensuring seamless transitions during disruptions.  

6. Cost Efficiency Without Compromise: By eliminating the need for dedicated DR infrastructure, RAS significantly reduces capital expenditure while delivering enterprise-grade resilience.  

From Strategy to Execution: Why RAS is Central 

The shift from uptime to resilience is not just conceptual – it requires execution. Organizations need: 

  • Continuous monitoring  
  • Automated orchestration  
  • Regular DR testing  
  • Expert management  

Yntraa RAS brings all these elements together into a single, unified service. It enables businesses to move from reactive recovery to proactive resilience, ensuring systems are always prepared for disruption. 

Cost vs Performance: How to Choose the Right Managed Database Tier for Your Workloads

In modern cloud architectures, databases are no longer passive storage systems they are active performance engines. Application responsiveness, customer experience, analytics speed, and even AI pipelines depend directly on how well your database layer is sized and structured.

Yet one of the most persistent engineering challenges remains the same: balancing cost and performance.

Overprovisioning leads to runaway cloud bills. Under provisioning causes latency spikes, replication lag, and frustrated users. The key lies in understanding how workload behavior, architecture and growth patterns translates into resource consumption.

Rising demand for AI infrastructure has increased pressure on compute and memory resources across cloud environments that is why database tier selection should be an engineering decision, not a procurement default.

Why Tier Selection Matters

Managed Database as a Service (DBaaS) platforms simplify operations patching, backups, failover, monitoring but they don’t eliminate architectural responsibility. Every tier you choose affects:

  • Query latency
  • Throughput capacity
  • Replication performance
  • Backup costs
  • Scaling flexibility

And importantly, costs in DBaaS environments do not scale linearly. Moving from 4 vCPU to 16 vCPU isn’t just 4× cost it often triggers higher IOPS, memory pricing, replication overhead, and backup storage increases.

Tier selection defines both your performance ceiling and your cost trajectory.

Understand Your Workload Before Choosing a Tier

The most common mistake teams make is sizing based on peak traffic guesses rather than workload characteristics.

A structured workload assessment should examine:

  • Transactions per second (TPS) or queries per second (QPS)
  • Read-to-write ratio
  • Concurrency levels
  • Data growth rate
  • Query complexity and indexing
  • Latency sensitivity

But more importantly, workloads should be classified.

A financial OLTP system handling thousands of ACID-compliant transactions per second behaves very differently from:

  • A search indexing pipeline ingesting logs
  • A product catalog serving 90% read traffic
  • A gaming leaderboard requiring real-time updates
  • A caching layer supporting millions of session reads

Each of these workloads stresses different dimensions of infrastructure CPU, memory, I/O, or network.

Tier selection begins with identifying which resource dimension dominates.

Identify the Real Bottleneck: CPU, Memory, or I/O?

Not all performance problems are compute problems. In many environments, database performance issues are not caused by insufficient compute but by mismatches between workload patterns and infrastructure tier characteristics.

  • CPU-bound workloads: Complex joins, analytics queries, heavy aggregations
  • Memory-bound workloads: Large working sets, caching layers, in-memory databases
  • I/O-bound workloads: Write-heavy systems, search engines, logging pipelines

For example, selecting a high-memory instance for a workload that is actually I/O-bound results in wasted spend. Conversely, upgrading storage when the bottleneck is CPU will not fix query latency.

With the integration of AI features, many workloads now involve Vector Search. Unlike standard B-tree indexes, vector indexes (such as HNSW) are extremely memory-intensive and often perform best when stored in memory to maintain low-latency similarity search. If your workload involves RAG (Retrieval-Augmented Generation), you must prioritize Memory-Optimized Tiers even if your transaction volume is low, to avoid disk-swapping during similarity searches.

Understanding bottlenecks prevents reactive scaling and unnecessary cost escalation.

Choose the Right Scaling Strategy

Database tiers typically scale in two ways:

  1. Vertical scaling (scale-up): Increasing CPU, RAM, or storage on a single node.
  2. Horizontal scaling (scale-out): Adding replicas or distributed nodes.

Relational databases often scale vertically first, particularly for consistency-sensitive workloads. Distributed and NoSQL systems are designed for horizontal expansion.

However, vertical scaling becomes exponentially expensive at higher tiers. Sometimes adding read replicas or sharding data can deliver better performance-per-dollar than upgrading a single large node.

The right scaling model depends on your database engine, workload pattern, and tolerance for architectural complexity.

Hidden Cost Drivers in DBaaS Tiers

Compute is only part of the bill.

True cost-performance analysis must account for:

  • Storage type (general SSD vs NVMe): Different storage classes deliver different latency and throughput levels. NVMe-based storage provides significantly higher I/O performance and lower latency and suitable for write-heavy workloads and search indexing systems. However, it also comes at a higher cost.
  • Provisioned vs burst IOPS: Some storage tiers provide a fixed number of I/O operations per second (IOPS), while others allow short bursts of higher performance when demand spikes. Provisioned IOPS ensure consistent performance for critical applications, whereas burst models are more cost-efficient for workloads with intermittent activity.
  • Replication architecture (synchronous vs asynchronous): Synchronous replication ensures that data is written to multiple nodes before a transaction is acknowledged, improving durability but adding write latency and infrastructure cost. Asynchronous replication is cheaper and faster but may allow brief data lag between nodes.
  • Cross-zone data transfer: High availability deployments often replicate data across availability zones. While this improves resilience, it also introduces additional network transfer costs and latency overhead.
  • Backup retention policies: Frequent backups and long retention periods increase storage consumption over time. While these policies strengthen disaster recovery capabilities, they must be aligned with regulatory and operational requirements to avoid unnecessary cost accumulation.
  • Snapshot storage growth: Periodic database snapshots accumulate over time, especially for large datasets. Without lifecycle management policies, snapshot storage can quietly grow into a significant portion of the monthly bill.
  • The Memory Premium of 2026: Due to the global shortage of high-bandwidth memory (HBM) driven by AI server demand, memory-optimized tiers have seen the sharpest price increases this year. When choosing a tier, audit your Buffer Pool usage strictly. If you can optimize your queries to use 20% less RAM, you might avoid a tier jump that now costs significantly more than it did a year ago.

High availability configurations improve resilience but increase infrastructure and write overhead. Aggressive backup retention policies may double storage costs over time.

Cost optimization does not mean reducing resilience it means aligning policies with workload value

When to Upgrade a Tier

Tier upgrades should be data-driven and sustained signals, not short-term spikes.

Warning signals include:

  • CPU utilization consistently above 70–80%
  • Memory pressure causing swapping
  • Increasing replication lag
  • Persistent I/O queue depth
  • User-facing latency during predictable load peaks

Conversely, if resource utilization rarely exceeds 30–40%, the environment may be oversized.

A mature managed database strategy continuously monitors metrics and aligns scaling decisions with actual usage trends. In 2026, we are moving from reactive scaling to Predictive Tiering. Modern managed database platforms increasingly use predictive monitoring to anticipate scaling needs before performance degradation occurs.

Choosing the Right Database Model Impacts Tier Economics

Tier selection cannot be separated from database architecture.

Relational systems offer strong consistency, structured schemas, and transactional guarantee, ideal for financial systems, ERP platforms, and regulated environments.

Non-relational systems prioritize scale and flexibility, document stores, wide-column databases, search engines, and key-value systems handle high-ingest, distributed, or real-time workloads more cost-efficiently at scale.

Forcing a relational database to ingest millions of event logs per second may require expensive vertical scaling, while a distributed NoSQL system could handle the same workload with horizontal expansion at lower cost.

Choosing the wrong database model often leads to unnecessary tier escalation.

How Yntraa Cloud Structures Database Tiering

Yntraa Cloud structures its managed database offerings around both database architecture and infrastructure tiering, allowing organizations to match performance characteristics with workload requirements.

At the platform level, database engines are grouped into two service families:

1. SutraDB (Relational DB Portfolio): Supports MySQL, PostgreSQL, MSSQL, and MariaDB. Designed for structured workloads with vertical scaling options, high-availability configurations, automated backups, and multi-zone resilience.

For regulated sectors such as BFSI and government, deployment within India-based sovereign cloud regions ensures data residency compliance while maintaining enterprise-grade performance.

2. FlexiDB (Non-Relational DB Portfolio):
Supports MongoDB, Redis, Cassandra, OpenSearch, Elasticsearch, Hadoop, ScyllaDB, and Couchbase.

These engines are optimized for horizontal scaling, caching layers, analytics pipelines, search workloads, and high-volume ingestion. The architecture supports clustering, replication, and scaling while reducing the operational burden of distributed database management.

Within each portfolio, database deployments can be provisioned across different infrastructure tiers depending on workload demands.

Typical tier options include:

1. General Purpose Compute: Balanced CPU, memory, and storage configurations suitable for most application workloads and development environments.

2. Memory Optimized Tiers: Designed for workloads where large in-memory datasets or caching layers are critical, such as Redis clusters or analytical query processing.

3. Storage Optimized Tiers: Built for high-throughput ingestion or search indexing workloads where disk I/O performance is the primary constraint.

By combining these infrastructure tiers with the appropriate database engine and scaling model, organizations can align cost and performance with the specific demands of each workload.

Conclusion: Tiering is an Architectural Decision

Choosing the right managed database tier is not about maximizing performance or minimizing cost in isolation. It is about aligning resource architecture with workload value.

Performance without cost discipline is unsustainable. Cost reduction without architectural awareness introduces risk.

When workload profiling, bottleneck analysis, scaling strategy, and database model selection are evaluated together, database tiering becomes a deliberate engineering decision, one that transforms infrastructure from a reactive expense into a strategic advantage.

A Comparison of Leading Managed Database as a Service (DBaaS) Providers: Key Features and Market Landscape

As organizations accelerate their cloud adoption, managing databases internally is becoming increasingly complex and resource intensive. Managed Database as a Service (DBaaS) platforms simplify this challenge by abstracting operational tasks such as infrastructure provisioning, patching, scaling, high availability, and backup management. By offloading these responsibilities to cloud providers, organizations can focus on application development and innovation rather than database operations.

Databases also play a critical role in powering modern digital initiatives such as artificial intelligence (AI), machine learning (ML), and real-time analytics. These technologies rely on reliable, scalable, and well-managed data infrastructure to store and process structured and semi-structured data at scale.

In this blog, we explore some of the leading DBaaS providers and how their database portfolios support a range of enterprise workloads—from traditional relational systems to modern distributed and NoSQL architectures.

Amazon Web Services (AWS)

AWS offers one of the most extensive DBaaS portfolios in the industry, covering relational, NoSQL, in-memory, graph, and time-series databases.

Relational services such as Amazon RDS support engines like MySQL, PostgreSQL, SQL Server, Oracle, and MariaDB. Amazon Aurora, AWS’s cloud-native relational database compatible with MySQL and PostgreSQL, is designed with a decoupled storage-compute architecture and six-way replication across three Availability Zones to deliver high availability and performance.

AWS also provides DynamoDB, a fully managed NoSQL database designed for single-digit millisecond latency at any scale, along with ElastiCache for Redis and Memcached-based in-memory workloads. Other specialized services include DocumentDB (MongoDB-compatible document database), Neptune for graph workloads, and Timestream for time-series data.

In 2026, AWS expanded its portfolio with Amazon Aurora DSQL, a serverless distributed SQL database for virtually unlimited scale for transactional workloads. Furthermore, through Amazon Bedrock integration, AWS databases now serve as native vector stores with automated RAG (Retrieval-Augmented Generation) pipelines, allowing developers to link operational data directly to foundation models.

These services are well suited for organizations building globally distributed applications and those already operating within the AWS ecosystem.

Microsoft Azure

Microsoft Azure provides a comprehensive set of managed database services designed for enterprise and hybrid cloud environments.

Azure SQL Database offers a fully managed relational database platform with built-in high availability, advanced security capabilities, and elastic scaling. As of late 2025, Azure SQL Database and Managed Instance now feature a native VECTOR data type and DiskANN-based vector indexing technology, enabling high-performance semantic search directly within the relational engine without needing external plugins. Azure Cosmos DB is a globally distributed multi-model database that supports multiple APIs including SQL, MongoDB, Cassandra, Gremlin (graph), and Table. It is designed for single-digit millisecond latency at the 99th percentile depending on workload configuration.

Azure also provides managed open-source databases such as Azure Database for PostgreSQL, MySQL, along with Azure Cache for Redis for high-performance caching.

Azure’s DBaaS portfolio is particularly attractive for enterprises deeply integrated with Microsoft technologies or operating hybrid infrastructure environments.

Google Cloud Platform (GCP)

Google Cloud offers a mix of relational, distributed, and analytical database services optimized for modern cloud-native workloads.

Cloud SQL provides managed MySQL, PostgreSQL, and SQL Server instances with high availability and automated maintenance. Cloud Spanner, Google’s globally distributed relational database, combines horizontal scalability with strong consistency which now includes Spanner Graph, a multi-model capability that supports ISO GQL (Graph Query Language). This allows organizations to perform complex relationship mapping and ‘GraphRAG’ enabling graph analytics alongside vector search for advanced AI-driven applications.

Google also offers Firestore, a serverless document database for application development, and Memorystore, which provides Valkey, Redis and Memcached for low-latency caching. Bigtable supports large-scale operational workloads, while AlloyDB, a PostgreSQL-compatible service, delivers enhanced performance and AI integration capabilities.

These services are particularly suited for organizations building intelligent applications that integrate closely with Google’s data analytics and AI ecosystem.

DigitalOcean

DigitalOcean provides simplified managed database services designed primarily for startups and small-to-medium businesses.

Its DBaaS offerings include managed PostgreSQL, MySQL, Valkey, OpenSearch and MongoDB deployments with built-in automated backups, failover capabilities, and simplified scaling. DigitalOcean emphasizes ease of use, predictable pricing, and developer-friendly infrastructure, making it a popular choice for early-stage companies seeking minimal operational overhead.

IBM Cloud

IBM Cloud provides enterprise-focused DBaaS solutions that combine open-source database engines with proprietary technologies.

Services such as IBM Db2 on Cloud are designed for high-performance transactional and analytical workloads, while IBM also offers managed versions of PostgreSQL, MongoDB, Redis, and Elasticsearch. IBM’s platform is particularly strong in regulated industries including banking, insurance, and telecommunications, where governance, auditability, and hybrid cloud integration are critical.

Vendor-Native DBaaS: A Quick Overview

In addition to cloud-provider offerings, many database vendors now provide their own managed services tailored specifically for their technologies. Examples include MongoDB Atlas, Redis Enterprise Cloud, Oracle Autonomous Database, and Couchbase Capella.

These vendor-native services often provide the most optimized experience for their respective database engines, including advanced features and performance optimizations. However, they typically focus on a single database technology and may lack unified management and flexibility provided by multi-database cloud platforms.

Organizations looking to leverage a specific database’s full potential may opt for vendor-native DBaaS. However, for most enterprises needing operational consistency, cost management, and choice across databases, multi-cloud DBaaS providers or platforms like Yotta offer greater flexibility.

Yotta’s Managed Database as a Service under Yntraa Cloud

Yotta’s comprehensive Managed Database as a Service (MDBaaS) offering on the Yntraa Cloud platform, designed to serve enterprises, startups, and public sector organizations with fully managed databases hosted within India’s sovereign data centers.

The platform will support a wide range of database technologies including MySQL, PostgreSQL, Microsoft SQL Server, MariaDB, MongoDB, Redis, Cassandra, Elasticsearch, OpenSearch, Hadoop, ScyllaDB, and Couchbase covering relational, non-relational and vector database workloads.

Yntraa Cloud’s MDBaaS will provide centralized monitoring, automated backups, high availability, patch management, security hardening, and scaling capabilities through a unified management platform with both API and graphical interfaces.

Built to support sectors such as BFSI, healthcare, manufacturing, and government, the service emphasizes data residency, enterprise SLAs, low-latency access within India. With compliance aligned to regulations such as Digital Personal Data Protection (DPDP) Act 2023, Yotta’s MDBaaS ensures that sensitive enterprise and citizen data remains within Indian bordersand also aligning with national initiatives such as Digital India and Make in India.

As organizations evaluate their database strategies, the choice of DBaaS provider increasingly depends on factors such as ecosystem alignment, scalability requirements, compliance needs, and operational simplicity. Organizations looking to leverage a specific database’s full potential may opt for vendor-native DBaaS, While hyperscalers offer extensive global platforms, regional providers like Yotta bring unique advantages in data sovereignty, regulatory alignment, and localized performance. As AI-driven workloads continue to grow, selecting the right database platform will remain a critical architectural decision for enterprises worldwide.

ProviderKey Strength (2026)
AWSEcosystem Depth
AzureEnterprise Microsoft Ecosystem
GCPAnalytics/Big Data
YottaData sovereignty & cost predictability
DigitalOceanSimplicity & predictable pricing

The Role of Cloud Assure Services in Strengthening Digital Operations 

Cloud adoption has removed traditional barriers to infrastructure like compute, storage, and networking are now abundant. Yet, as digital environments grow more complex, maintaining operational stability in the cloud remains a pressing challenge. 

Downtime today is rarely caused by a single system failure. It is more often the result of fragmented visibility, delayed detection, unclear ownership, or silent SLA breaches. In this environment, cloud assure services play a quiet but increasingly essential role. Their focus is less on enabling cloud and more on making it operationally trustworthy. 

The Operational Reality Behind Cloud-First Setups 

It’s rare to find an enterprise running just a single cloud workload today. The reality is much messier: applications are sprawled across different environments, hooked into third-party services, and serving users who have zero tolerance for downtime. While cloud platforms promise resilience on paper, the day-to-day reality is often a struggle. Teams usually don’t catch performance hits until a user complains. Alerts fire off without context; real-time SLA tracking is often just a wish and it’s becoming harder to pin down who owns a problem as systems scale. These blind spots kill reliability, even if the underlying infrastructure is rock solid. 

Why Business Continuity in Cloud Needs More Than Redundancy 

When organisations discuss business continuity on the cloud, the conversation often stops at backup or disaster recovery. While necessary, these measures are reactive by nature. Continuity also depends on day-to-day operational health, including detecting early signs of degradation, validating service availability, and ensuring consistent performance under load. 

Without structured assurance, continuity becomes an assumption rather than a measurable outcome. 

Working Backwards from the Pain Points 

Instead of adding more tools or dashboards, many organisations are rethinking operations from a service-outcome perspective. This shift is where cloud assure solutions become relevant. 

Rather than focusing on isolated metrics, assurance frameworks ask broader questions: 

  • Is the service usable right now? 
  • Are we trending toward an SLA breach? 
  • Will this issue escalate if left unaddressed? 
  • Can teams act quickly with the information available? 

By working backwards from operational failures, assurance models address root causes rather than symptoms. 

From Alerts to Assurance 

Traditional monitoring tells teams when thresholds are crossed. Assurance correlates signals across infrastructure, applications, and networks to indicate whether a service is at risk, often before users notice. 

From Assumed SLAs to Measured SLAs 

Many organisations review SLAs retrospectively after incidents have already occurred. Continuous SLA monitoring in cloud services introduces real-time accountability and enables teams to course-correct early. 

From Reactive Operations to Predictable Operations 

Firefighting does not scale. Assurance services standardize how issues are detected, escalated, and resolved, reducing dependency on individual expertise and improving consistency across environments. 

Strengthening Reliability Without Increasing Complexity 

Ironically, attempts to improve reliability often increase operational noise. Multiple dashboards, overlapping alerts, and disconnected reports make it harder to see what matters. 

Effective cloud assure services simplify rather than add layers. By focusing on service health and operational outcomes, they help teams prioritise actions that protect uptime and performance, which are key drivers of cloud infrastructure reliability. 

This approach directly supports faster issue detection, reduced average time to resolution, fewer user-facing incidents, and greater confidence during scaling or peak usage. 

Assurance as an Ongoing Operational Discipline 

Cloud environments are not static. Applications evolve, workloads scale, and usage patterns shift. Assurance cannot be a one-time setup. It must adapt continuously. 

This is why assurance works best when embedded into daily operations rather than treated as a standalone initiative. Some providers approach this quietly, positioning assurance as an operational layer that supports stability without drawing attention to itself. For instance, Yntraa Cloud incorporates cloud assurance into how environments are monitored, governed, and supported, so reliability improves without customers having to manage yet another operational surface. Its Cloud Assure Services focus on maintaining day-to-day operational stability through continuous visibility, structured governance, and proactive issue identification. By aligning infrastructure performance with service-level expectations, the approach helps organizations sustain availability, manage risk, and support business continuity as cloud environments scale. 

When assurance is effective, it is rarely noticed. What is noticed instead is steadier performance, fewer escalations, and predictable service behaviour. 

The Bigger Picture: Trust in Digital Operations 

At scale, digital operations run on trust. Trust that applications will be available, that performance will hold under pressure, and that issues will be addressed before they become visible failures. 

By addressing operational pain points such as visibility gaps, reactive incident management, and unmeasured SLAs, cloud assure services help organisations move beyond simply running workloads in the cloud. They help ensure those workloads are dependable enough to support the business. 

In a cloud-first world, reliability is no longer an infrastructure concern alone. It is an operational responsibility, and assurance is what quietly sustains it.

Understanding Compute as a Service: What It Means for Businesses in the Cloud Era 

For most enterprises, compute has shifted from being a fixed asset on the balance sheet to a programmable capability embedded in the business. As digital transformation accelerates, legacy infrastructure models – defined by heavy capital investment, long procurement cycles, and capacity planned years in advance – are proving incompatible with today’s pace of change. In response, consumption-based models have moved from cost optimization tools to strategic enablers, positioning compute as a service (CaaS) at the core of modern IT architectures. 

At a functional level, CaaS provides on-demand access to processing power with elastic scaling and usage-based pricing. Its real impact, however, is architectural rather than operational. By decoupling compute from physical infrastructure, CaaS reshapes how applications are built, how workloads are orchestrated, and how organizations absorb demand volatility. Compute becomes something that can be dynamically composed, automated, and optimized in real time – allowing businesses to align technology capacity directly with business outcomes, rather than with static forecasts.

From Infrastructure Ownership to Compute Consumption 

Early cloud adoption largely replicated on-premise thinking in a virtualized form. Physical servers were replaced by virtual machines, but operating models, capacity assumptions, and governance structures remained anchored to data center era practices. The cloud was treated as a hosting environment rather than a fundamentally different way to consume compute. That phase is now decisively behind us.

Modern cloud computing services prioritize abstraction, automation, and elasticity as first – class design principles. The unit of management has shifted from servers to workloads, and from infrastructure uptime to application performance and cost efficiency. Capacity is no longer provisioned for theoretical peak demand; it is continuously adjusted based on real-time signals. In this model, compute is not an owned resource to be maintained, but a consumable service that can be programmatically allocated, scaled, and retired.

This shift becomes critical in environments where demand patterns are volatile or non-linear. Seasonal retail spikes, bursty financial transactions, and fast-scaling SaaS platforms require scalable cloud compute that responds instantly to workload behavior rather than human planning cycles. CaaS enables this responsiveness, allowing organizations to absorb uncertainty without over-provisioning, while maintaining performance, reliability, and cost discipline. 

The CaaS Evolution: AI Changes Everything 

As we head into 2026, the evolution of CaaS is being driven decisively by AI. AI workloads place fundamentally different demands on compute infrastructure compared to traditional enterprise applications. They require high parallelism, accelerated processing, fast interconnects, and the ability to scale both vertically and horizontally. 

This has pushed CaaS platforms to expand beyond general – purpose compute into a spectrum of virtual compute services, including GPU – backed instances, bare metal options, container – native environments, and serverless execution models. The goal is not just to provide raw compute, but to align the right type of compute with the right workload. 

Equally important is orchestration. AI pipelines span data ingestion, training, inference, and continuous optimization. Managing these manually is inefficient and error-prone. Modern CaaS platforms increasingly rely on Kubernetes, workflow engines, and policy-driven schedulers to automate workload placement, scaling, and failover – reducing operational overhead while improving performance consistency. 

Platform – Level Automation Becomes the Differentiator 

As compute environments grow more complex, automation is no longer optional. Customers now expect platforms to handle provisioning, scaling, patching, monitoring, and optimization with minimal manual intervention. This is where the distinction between commodity infrastructure and the best cloud computing services becomes clear. 

Leading CaaS platforms embed automation at the platform level. Infrastructure is provisioned through APIs, scaling is driven by real-time telemetry, and cost controls are enforced through usage policies rather than human oversight. Observability is integrated by default, giving teams visibility into performance, cost, and reliability without stitching together multiple tools. 

For enterprises running AI-driven workloads, this level of automation is essential. Model training jobs need to spin up massive compute clusters temporarily and shut them down just as quickly. Inference workloads must scale instantly in response to user demand. Without intelligent orchestration and automation, the economics of AI simply don’t work. 

Yntraa Compute as a Service: Built for What’s Next 

This is where Yntraa Cloud Compute positions itself differently. At the core of the Yntraa cloud ecosystem, Compute as a Service is designed to support the full spectrum of modern workloads – ranging from end – user compute and virtual machines to bare metal, containers, managed Kubernetes, and serverless execution. 

Rather than forcing enterprises into a single compute paradigm, Yntraa enables organizations to choose the most appropriate environment for each workload while maintaining centralized governance, security, and observability. This approach is particularly relevant as businesses increasingly run AI, analytics, and digital services side by side. 

Yntraa’s platform-level automation and orchestration capabilities are built to handle this complexity. Rapid provisioning, automated scaling, integrated monitoring, and policy-driven cost controls allow teams to focus on innovation rather than infrastructure management. Security and compliance are embedded into the platform through centralized identity, encryption, audit logging, and regulatory alignment – making it suitable for enterprises, governments, and regulated industries. 

A CaaS Platform Aligned with 2026 Realities 

As organizations look ahead to 2026, the expectations from compute platforms are clear: support AI – native workloads, simplify orchestration, ensure predictable costs, and preserve data sovereignty. Yntraa Compute as a Service addresses these needs through a resilient, region-aware architecture, multiple deployment models, and a strong emphasis on operational excellence. 

Adopting a Multi-Cloud Strategy: How Cloud MSPs Empower Businesses with Flexibility and Vendor Independence

Organisations are increasingly embracing a multi-cloud strategy to drive agility, mitigate risks, and enhance performance. A multi-cloud approach, which involves leveraging two or more cloud service providers (CSPs), offers flexibility, resilience, and freedom from vendor lock-in. As businesses navigate this complex environment, Cloud Managed Service Providers (MSPs) have emerged as strategic enablers, helping enterprises maximise the benefits of multi-cloud while minimising its challenges.

The Shift Towards Multi-Cloud Environments

Traditionally, businesses relied on a single cloud vendor to host their workloads, data, and applications. However, as operations become more global, digital, and compliance-driven, the drawbacks of a single-vendor dependency, like limited customisation, regional outages, and pricing inflexibility, have become apparent.

According to Flexera’s 2024 State of the Cloud Report, 93% of enterprises have implemented a multi-cloud approach, with 87% embracing hybrid cloud models that combine both public and private cloud services. This shift is driven by the need for enhanced flexibility, risk mitigation, and performance optimisation.

Enter the multi-cloud strategy.

With multi-cloud, organisations can:

  • Distribute workloads across different CSPs (e.g., AWS, Azure, Google Cloud) for optimal performance.
  • Mitigate downtime risks by avoiding reliance on one provider.
  • Leverage the best-in-class services from different vendors (e.g., Google’s AI/ML capabilities, Azure’s enterprise integrations).
  • Comply with regional data regulations by hosting data across multiple geographies.

Yet, managing a multi-cloud environment is no small feat—it introduces complexity in operations, security, and cost management. This is where Cloud MSPs play a crucial role.

How Cloud MSPs Empower Multi-Cloud Success

Cloud Managed Service Providers act as trusted partners that design, deploy, and manage multi-cloud architectures tailored to specific business needs. Here’s how they empower organisations with flexibility and vendor independence:

  1. Simplified Cloud Management: MSPs unify the management of disparate cloud platforms under a single pane of glass. They provide tools and dashboards that give visibility into usage, performance, and costs across cloud environments. This consolidation ensures businesses don’t need separate teams or tools for each cloud provider.
  2. Workload Optimisation & Portability: One of the biggest advantages of multi-cloud is the ability to run the right workload on the right cloud. MSPs assess application requirements and help businesses map them to the ideal cloud platform, optimising performance, and cost. Moreover, they enable workload portability—helping businesses move applications or data between clouds without re-architecting. This significantly reduces vendor lock-in and enhances operational agility.
  3. Security & Compliance: Multi-cloud security can be complex due to varying security models and compliance standards across providers. MSPs bring in standardised security practices, continuous monitoring, and threat intelligence. They also ensure alignment with industry regulations like GDPR, HIPAA, or India’s Data Protection Bill.
  4. Disaster Recovery & High Availability: MSPs design resilient architectures using multiple clouds to ensure redundancy and failover mechanisms. In case of an outage in one cloud, operations can shift seamlessly to another, ensuring uninterrupted service and business continuity.
  5. Cost Optimisation: Cloud sprawl is a common issue in multi-cloud setups. MSPs monitor resource utilisation, eliminate redundancies, and suggest cost-saving opportunities. Through rightsizing, reserved instances, and consumption insights, businesses can stay on budget without compromising performance.

Yotta: Driving Multi-Cloud Excellence in India

As a leading digital transformation and cloud services provider, Yotta is playing a pivotal role in helping Indian enterprises transition seamlessly to multi-cloud environments. With its robust ecosystem of data centers, cloud platforms, and managed services, Yotta offers businesses a vendor-agnostic and scalable foundation for cloud adoption. However, managing multiple cloud environments can introduce complexities in integration, security, and operations.

Yotta addresses these challenges through its Hybrid and Multi Cloud Management Services, offering a unified platform that seamlessly integrates private, public, hybrid, and multi-cloud environments. By providing a single-window cloud solution, Yotta simplifies cloud management, enhances scalability, and ensures robust security across diverse cloud infrastructures. This comprehensive approach empowers enterprises to manage their IT resources efficiently, adapt to evolving business needs, and drive digital transformation initiatives.

Here’s what sets Yotta apart:

  • Interoperability with major cloud providers.
  • Expert-led migration and deployment support.
  • End-to-end managed services including security, monitoring, and governance.
  • Localised data centers that comply with India’s data residency regulations.

Whether you’re a large enterprise or a fast-growing startup, Yotta ensures that your multi-cloud journey is efficient, secure, and aligned with business goals.

Conclusion: The future of multi-cloud offers the agility and resilience that modern enterprises need to stay competitive. However, to harness its full potential, organisations must overcome operational and technical complexities.

That’s where Yotta come in bridging the gap between strategy and execution and delivering a cloud experience that is secure and truly vendor-independent.

By partnering with the right MSP, businesses can turn multi-cloud from a complex challenge into a strategic advantage.

Best Practices for Managing Resources in a Multi-Cloud Environment 

Multi-cloud architecture is no longer an emerging trend; it’s an established reality. Recent industry reports show that nearly 90% of enterprises have embraced a multi-cloud strategy to leverage the unique strengths of different providers and enhance resilience. However, this strategic move introduces significant operational hurdles. The top challenge cited by a majority of these organisations is managing cloud spend, with an estimated 30% of cloud expenditure being wasted on inefficient resources. This complexity creates a critical need for a disciplined, technical approach to resource management.

Without a robust framework, the promise of multi-cloud agility can be quickly undermined by fragmented visibility, inconsistent security, and runaway costs. Successfully managing a distributed infrastructure requires moving beyond ad-hoc efforts to a cohesive, technology-driven strategy.

Technical Best Practices for Multi-Cloud Management 

To truly harness the power of a multi-cloud or hybrid cloud environment, organisations must implement a set of core technical disciplines.

  • Establish Unified Governance with Infrastructure as Code (IaC): In a multi-cloud setup, manual configuration is a direct path to security gaps and inconsistencies. The best practice is to manage your infrastructure programmatically using IaC tools like Terraform. By defining your resources—from virtual machines to network security groups—in version-controlled code, you create a single source of truth. This allows you to enforce standardised security policies, manage configurations, and ensure compliance across all cloud platforms automatically.
  • Implement Comprehensive Observability, Not Just Monitoring: Basic monitoring of CPU and memory is no longer enough. True visibility across a distributed environment requires observability the ability to analyse metrics, logs, and traces in a unified platform. Implementing a “single-pane-of-glass” observability solution is critical. It allows your teams to correlate performance issues and security events across your on-premises data center and multiple cloud providers, drastically reducing Mean Time to Resolution (MTTR) and identifying root causes that would otherwise remain hidden in data silos.
  • Enforce Proactive FinOps and Cost Optimisation: To combat the estimated 30% of wasted cloud spend, organisations must adopt a proactive financial operations (FinOps) model. This involves more than just monitoring a monthly bill.
  • Automated Scheduling: Implement “start/stop” schedules for non-production environments to ensure you’re not paying for idle development and testing resources during off-hours.
  • Continuous Rightsizing: Use performance data from your observability platform to continuously rightsize virtual machines and storage volumes, ensuring you pay only for the capacity you need.
  • Leverage Spot Instances: For fault-tolerant or batch-processing workloads, strategically using spot or preemptible instances can reduce compute costs by up to 90% compared to on-demand pricing.

The Strategic Accelerator: Cloud Management Services 

While establishing a FinOps culture and an IaC pipeline in-house is the goal, the reality is that it requires a rare and expensive combination of multi-platform expertise. The complexity multiplies in a hybrid cloud model, where bridging the operational gap between on-premises and public cloud systems is a persistent challenge. This is where expert Cloud Management Services act as a strategic accelerator. 

Engaging a specialised provider gives you immediate access to the certified expertise and sophisticated toolsets required to implement these technical best practices effectively and at scale. At Yotta, our Cloud Management Services are designed to function as an extension of your team. We provide the unified platform and proactive governance needed to bring order to your multi-cloud estate, allowing you to focus on innovation while we ensure your infrastructure is secure, compliant, and cost-efficient. 

 A multi-cloud strategy without a technically sound management framework is an incomplete strategy. It invites risk and inefficiency that negate the very benefits you seek to achieve. By implementing these technical best practices, you can transform your multi-cloud environment from a source of complexity into a powerful engine for business growth.